NVIDIA Elite Partner · Local AI Inference Workstation

Enterprise AI that runs
inside your walls.

Gabe IO delivers enterprise AI infrastructure through the GabeHERO product line. From the GabeHERO TX local AI inference workstation to the GabeHERO RX enterprise AI server, our solutions help organizations run AI workloads on-premises with greater control over their infrastructure, data, and deployment.

Explore Our Products Request More Information
2,070
TFLOPS (FP4) AI inference performance
128GB
Unified memory — runs 70B–120B parameter models
5min
Deployment time — arrives pre-configured, ready to run
$0
Recurring cloud token cost — one-time hardware investment

Built for the decisions that cannot leave the building.

Every GabeHERO deployment addresses a use case where cloud AI data exposure, runaway cost, or uptime dependency creates unacceptable business risk.

🏭
Manufacturing
Quality inspection, predictive maintenance, and process optimization — all running locally. Sensor data and production images never leave the facility. Operates independently of plant floor connectivity.
Manufacturing · GabeHERO TX
🚚
Logistics
Route optimization, demand forecasting, and warehouse automation — all running on-premises with zero cloud dependency. Sensitive shipment data, carrier contracts, and inventory levels stay inside the four walls of your operation.
Logistics · GabeHERO TX
🏢
Enterprise AI Agents
Power AI assistants and digital employees that automate complex business processes. With GabeHERO TX, agentic workflows run at a flat, predictable cost — no per-call fees, regardless of chain depth or volume.
Enterprise · GabeHERO TX
🛡️
Financial Services
Fraud detection requires a decision before the transaction clears. With on-premises inference, every transaction is screened locally — no data routed to external servers, no cloud round-trip latency. GabeHERO TX keeps financial data entirely within your institution.
Financial Services · GabeHERO TX
🧠
Sovereign AI Model Training
Fine-tune and serve large language models and industry-specific models — financial, legal, healthcare — entirely on-premises. Models, training data, and logs remain in your facility. Built for regulated industries where data cannot leave the building.
Data Center · GabeHERO RX
🤖
Embodied AI & Robotics
Train simulation and world model pipelines and robot models locally, then synchronise to edge devices. GabeHERO RX trains the models; GabeHERO TX deploys them — a complete edge-to-data-center AI pipeline under your control.
Robotics · GabeHERO RX

You cannot govern AI infrastructure you do not own.

Cloud AI was built to optimize for speed and scale across shared infrastructure. Data sovereignty, cost predictability, and enterprise privacy are the opposite of that. Gabe IO, Inc solves each one at the hardware layer.

Cloud AI cost compounds with every token
Every query, every agent sub-call, every document processed is metered. At enterprise scale, those costs become structural. GabeHERO TX is a one-time investment — no recurring fees, at any volume.
Your data leaves your facility
Cloud inference routes sensitive business data through shared infrastructure across multiple jurisdictions. With GabeHERO TX, inference runs where the data lives — on your hardware, inside your walls.
Cloud uptime is someone else's problem
When cloud AI goes down, your operations stop. GabeHERO TX runs fully offline — no internet dependency, no service interruptions, no single point of failure you don't control.
Sovereignty by design, not by policy
GabeHERO keeps data on-premises by architecture — not contractual promise. Complete control over your AI infrastructure, models, and data with zero third-party dependency.

GabeHERO Product Line

From the edge to the data center — a complete sovereign AI infrastructure stack, pre-installed with GabeIO OS and ready to deploy out of the box.
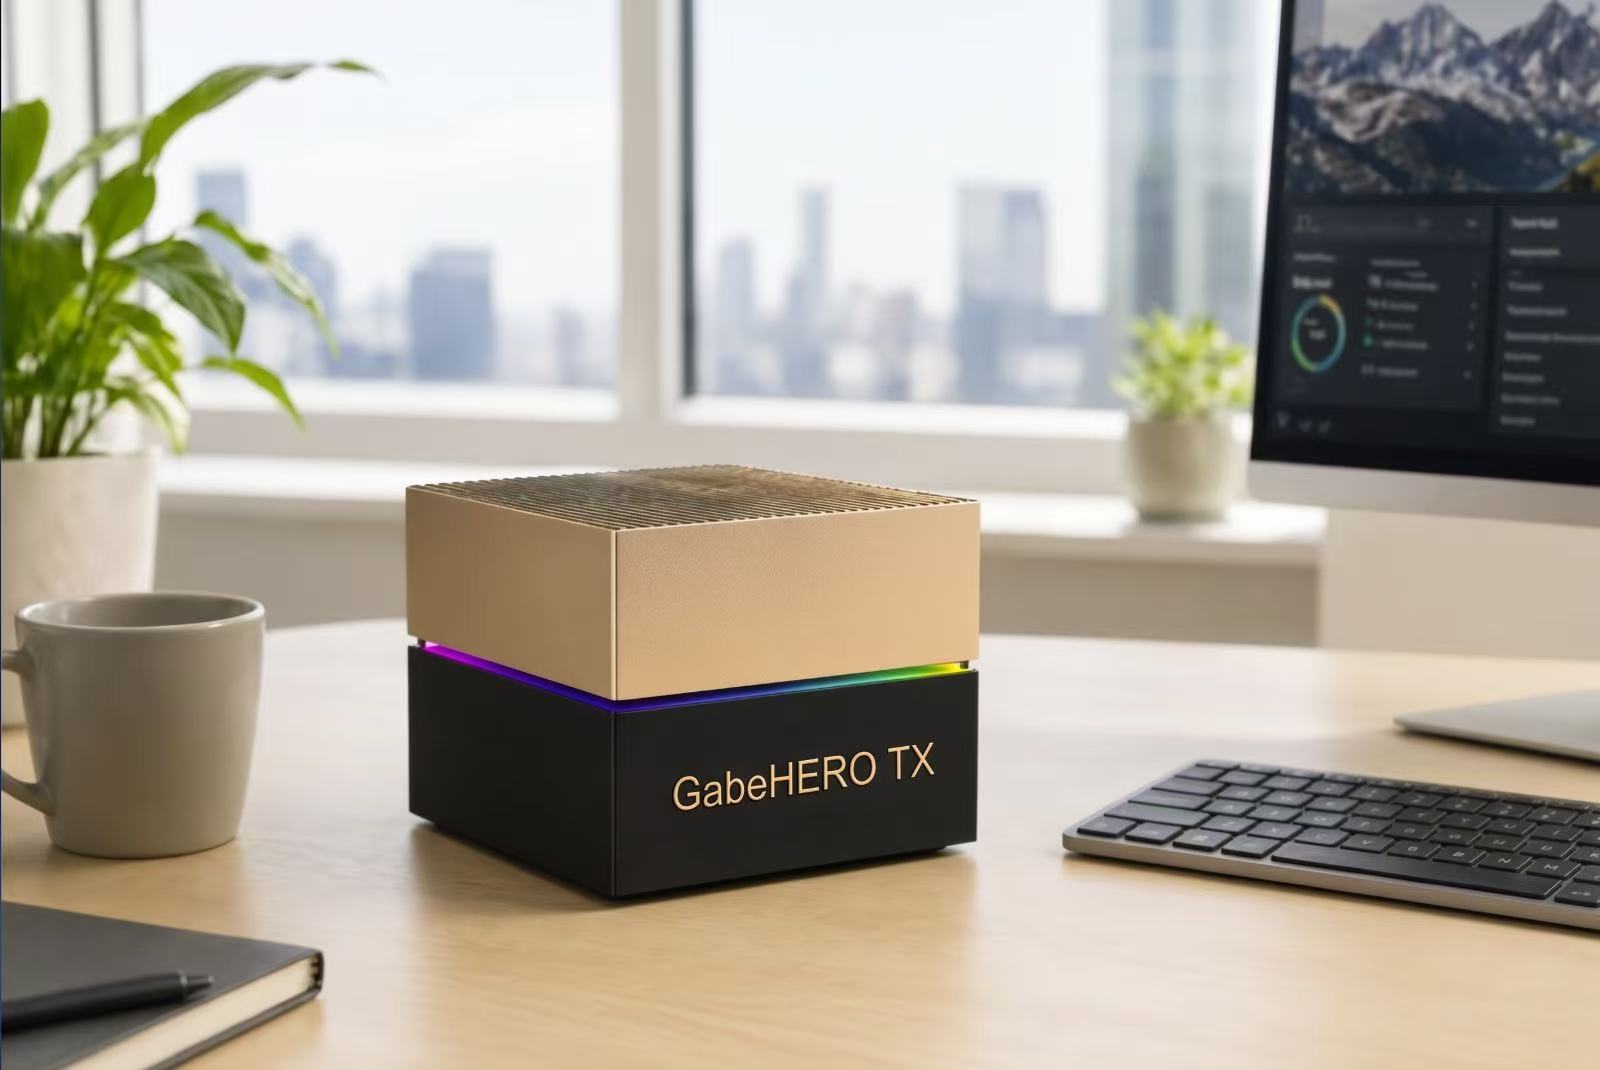
GabeHERO TX local AI inference workstation
LOCAL AI INFERENCE WORKSTATION
GabeHERO TX
Micro AI Factory — enterprise-grade local AI inference on a single unit, no cloud required
GPUNVIDIA Jetson Thor T5000 (Blackwell)
AI Performance2,070 TFLOPS (FP4)
Memory128 GB Unified Memory
Dimensions7.9 × 7.9 × 6.4 in
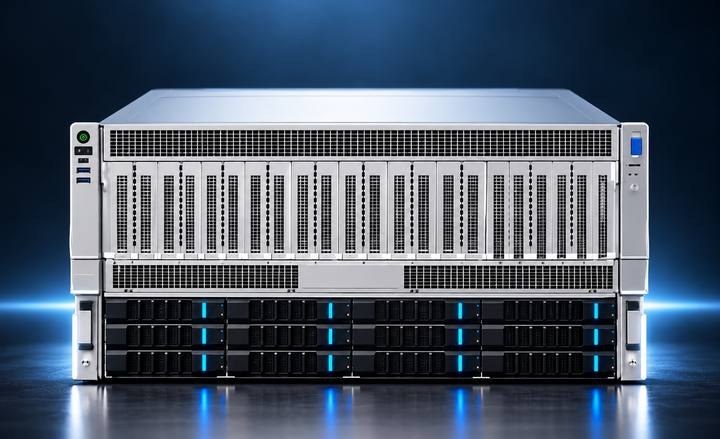
GabeHERO RX 6U rack-mount data center AI server
DATA CENTER AI SERVER
GabeHERO RX
Data Center AI Server for Private Infrastructure — Sovereign. Scalable. Out-of-the-Box.
GPUNVIDIA RTX PRO 6000 (Blackwell)
GPU CountUp to 8 × dual-width
Form Factor6U Rack Server
Power Supply8,000W


Everything you need to evaluate and deploy.

Technical documentation, datasheets, and guides for IT, procurement, and AI engineering teams.

📄
GabeHERO TX Datasheet
Full technical specifications for the GabeHERO TX local AI inference workstation. GPU, memory, connectivity, and software platform.
Request PDF →
🖥️
GabeHERO RX Datasheet
Full technical specifications for the GabeHERO RX data center AI server. GPU config, storage, expansion slots, cooling, and power.
Request PDF →
⚡
Deployment Guide
Step-by-step setup instructions for GabeHERO TX and RX. Network configuration, model loading, GabeIO OS administration, and MIG setup for RX.
Request access →

What customers report after deploying GabeHERO.

Across manufacturing, financial services, and enterprise deployments worldwide.

$0
Recurring cloud token cost after deployment. One-time hardware investment replaces per-query billing entirely.
<100ms
Inference latency for on-premises AI decisions — no round-trip to a cloud provider.
5 min
Time from unboxing to first inference on GabeHERO TX. No IT provisioning cycle required.